

Buying GPUs is not deploying AI.
Servers arrive, the rack lights turn green, but the hard part starts next. M37Labs architects private models, inference runtimes, and cluster operations—100% behind your corporate firewall.
Turning bare-metal compute into operational intelligence.
Unboxing servers is simple. But determining model sizing, tuning inference runtimes, orchestrating VRAM bandwidth, and managing 24/7 cluster operations is where private AI projects succeed or stall. M37Labs delivers the complete operational layer behind your corporate firewall.
The Journey from Racked Silicon to Deployed AI
Step through our 5-part visual breakdown of why buying GPUs is just step zero, and how M37Labs delivers the rest of the operational pipeline.
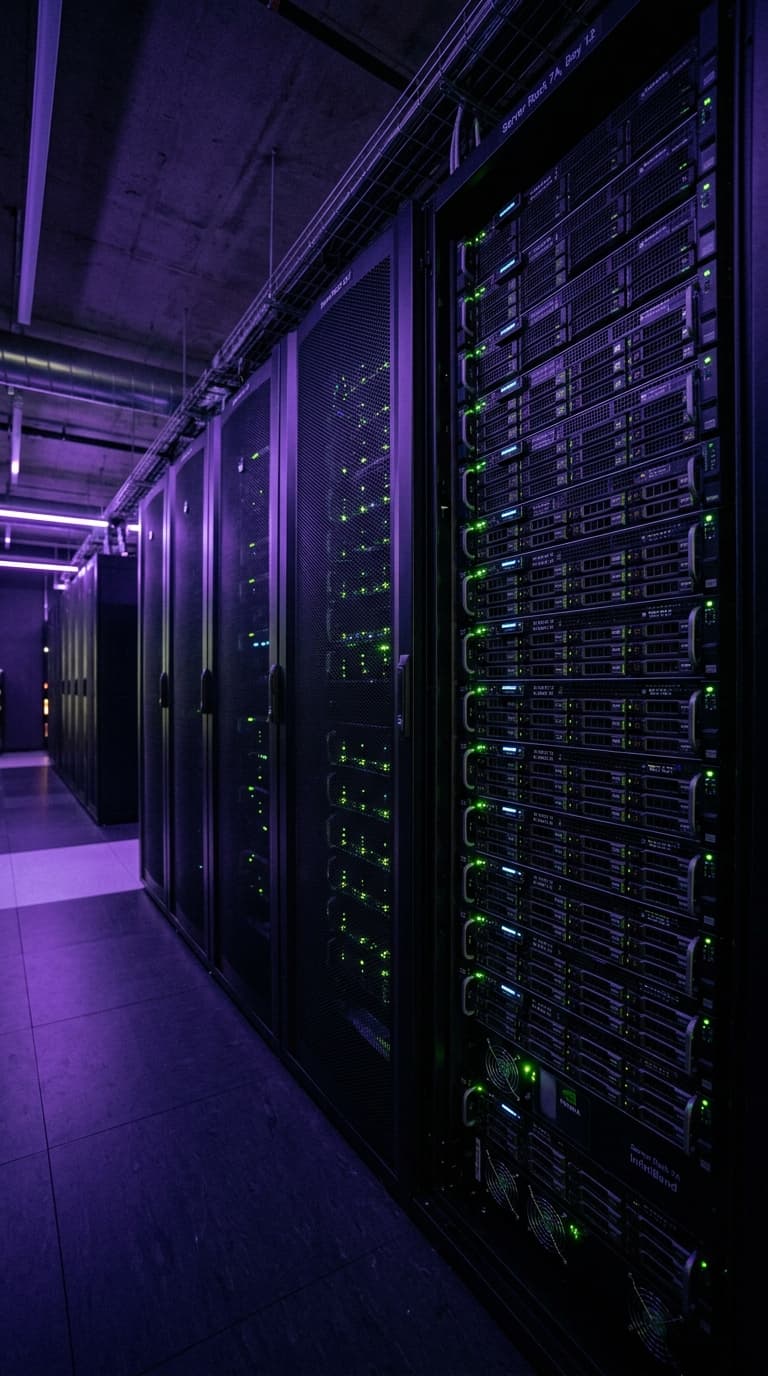
Buying GPUs ≠ Deployed AI
Servers arrive. The hard part starts next.
The GPUs are racked. The lights are green. Then someone in the review meeting asks, 'So...'
The Day-Two Reality of AI Procurement
Across enterprises, compute procurement outpaces software readiness by 12–18 months. Having servers physically racked does not translate into operational intelligence. Without model alignment, runtime orchestration, and workflow integration, raw FLOPs remain an expensive cost center.
The 4 Layers of AI Technology
To win the AI race, companies are fighting across an interconnected stack from end-user software down to physical silicon.
The Application Layer
Companies are racing to become the default interface of daily work, locking in high-retention enterprise workflows before underlying model intelligence becomes commoditized.
The 4 Layers of AI Technology
To win the AI race, companies are fighting across an interconnected stack—from end-user software down to physical silicon. Scroll down or select any layer to inspect the architectural battleground.
The Application Layer
Companies are racing to become the default interface of daily work, locking in high-retention enterprise workflows before underlying model intelligence becomes commoditized.
The Model Layer
Foundational labs are battling to build the highest-IQ reasoning models while simultaneously driving down the cost-per-million tokens by orders of magnitude.
The Infrastructure & Platform Layer
Hyperscalers and platforms are fighting to lock in multi-year compute commitments, capturing the immense data gravity and compute spend that underpins every AI workflow.
The Hardware Layer
Semiconductor titans and foundries are competing against the physical limits of physics: sub-2nm lithography, HBM3e memory yields, and securing multi-gigawatt power grid feeds.
Where M37Labs bridges the full stack.
Hyperscalers want your company to rent cloud compute forever, creating compounding egress costs and privacy exposure. When you buy private hardware, M37Labs delivers the operational software layer to connect physical silicon directly into sovereign enterprise workflows.
Model weights and inference execution never touch external clouds or public APIs.
Hyper-efficient local SLMs engineered for deterministic, high-throughput batching.
Thermal management, vLLM orchestration, CUDA tuning, and 24/7 cluster health.
Convert runaway API token bills into predictable, amortized compute assets.
Turn idle racks into operational advantage.
The servers have arrived. The lights are green. Let M37Labs architect the model topologies, inference engines, and 24/7 cluster operations to put private AI to work inside your enterprise.